

Steering Reward Hacking
Collection
Strongest suppressing and amplifying reward-hacking shifts for GLM-5.3-Flash and DeepSeek-V4.1-Flash. • 4 items • Updated
LLM Evaluation
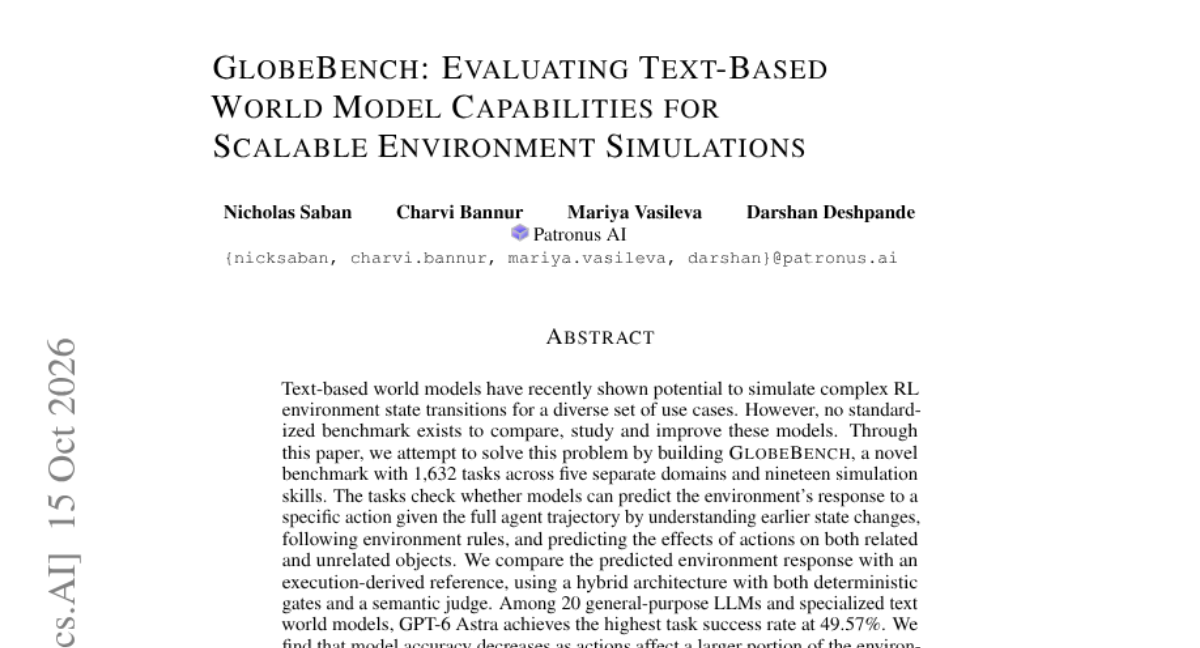
GlobeBench: Evaluating Text-Based World Model Capabilities for Scalable Environment Simulations
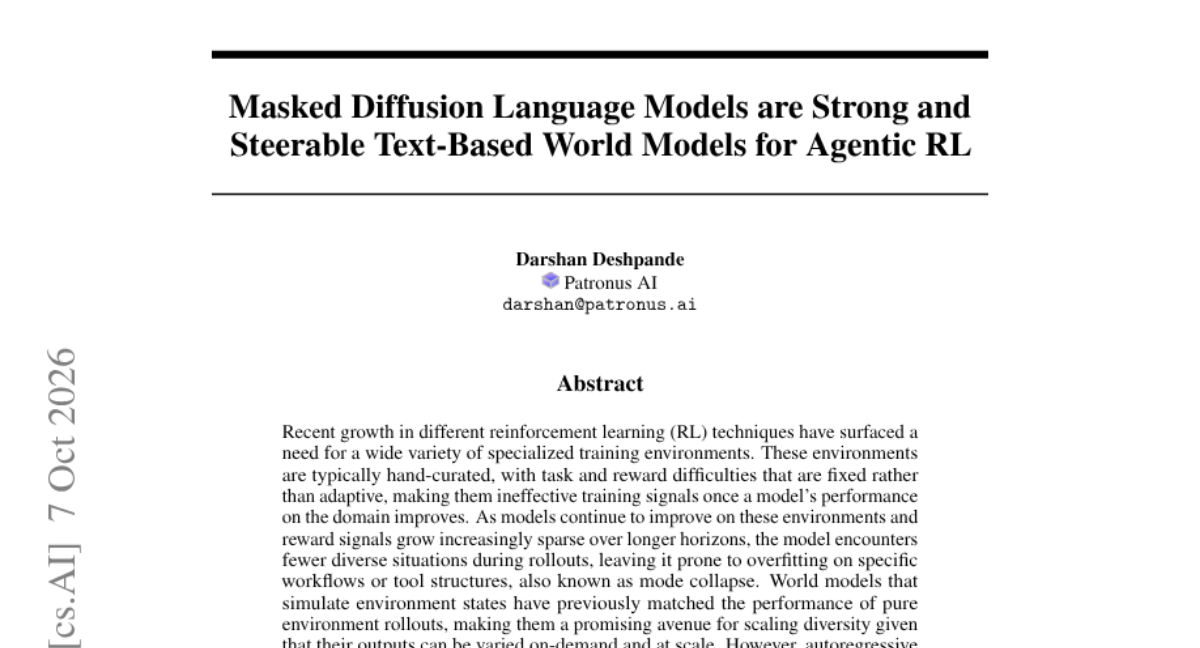
Masked Diffusion Language Models are Strong and Steerable Text-Based World Models for Agentic RL


