# Getting No log in validation\_loss
**URL:**
**Author:**  [@sai-santhosh](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2Fsai-santhosh)%5C
**Post date:** [February 14, 2025, 3:01pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Fgetting-no-log-in-validation-loss%2F140868%2F1 "2025-02-14T15:01:08Z")
```auto
from transformers import AutoModelForCausalLM, AutoTokenizer
model = AutoModelForCausalLM.from_pretrained(
"meta-llama/Llama-3.2-3B",
quantization_config = bnb_config,
trust_remote_code = True
).to(device)
tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.2-3B")
from peft import prepare_model_for_kbit_training, LoraConfig, get_peft_model
lora_config = LoraConfig(
r=8,
lora_alpha=32,
target_modules= ["q_proj", "k_proj", "v_proj", "o_proj", "gate_proj", "up_proj", "down_proj"],
lora_dropout=0.05,
bias="none",
)
model = prepare_model_for_kbit_training(model)
model = get_peft_model(model, lora_config)
from trl import setup_chat_format
model,tokenizer = setup_chat_format(model,tokenizer)
from trl import SFTConfig, SFTTrainer
args = SFTConfig(
output_dir = "lora_model/",
per_device_train_batch_size = 4,
per_device_eval_batch_size = 4,
learning_rate = 2e-05,
gradient_accumulation_steps = 2,
max_steps = 150,
logging_strategy = "steps",
logging_steps = 5,
save_strategy = "steps",
save_steps = 25,
eval_strategy = "steps",
eval_steps = 5,
lr_scheduler_type = "cosine",
fp16 = True,
data_seed=42,
max_seq_length = 2048,
report_to = "none",
)
trainer = SFTTrainer(
model = model,
args = args,
processing_class = tokenizer,
train_dataset = dataset['train'],
eval_dataset = dataset['test'])
```
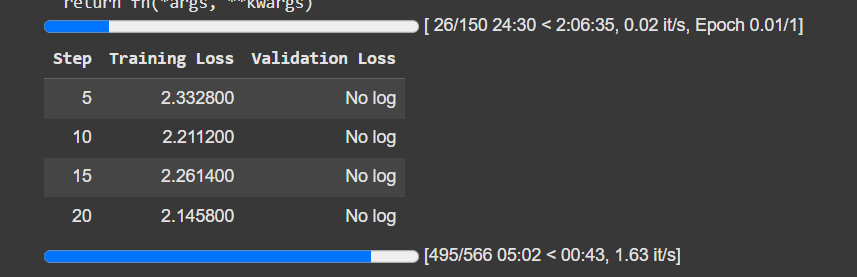
why am i getting no log for validation loss
---
**Author:**  [@John6666](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2FJohn6666)%5C
**Post date:** [February 14, 2025, 3:16pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Fgetting-no-log-in-validation-loss%2F140868%2F2 "2025-02-14T15:16:29Z")
Perhaps this?
> [@'No Log' for validation loss during training with Trainer](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Fno-log-for-validation-loss-during-training-with-trainer%2F40094)%3A
>
> Hello, I’m trying to fine-tune a Custom BertModel on a sequence classification task, but I’m having some issues getting the Trainer to log the validation loss. Specifically, the log looks like this: Here is the code I’m using: from datasets import load\_dataset import torch.nn as nn from transformers import ( AutoModel, AutoModelForSequenceClassification, AutoTokenizer, DataCollatorWithPadding, Trainer, TrainingArguments ) class CustomTrainer(Trainer):…
> For LLM validation loss you might also need `label_names=[]` in the TrainingArguments and set `trainer.can_return_loss = True` to satisfy [transformers/src/transformers/trainer.py at v4.40.2 · huggingface/transformers · GitHub](https://github.com/huggingface/transformers/blob/v4.40.2/src/transformers/trainer.py#L3796) for some models.
---
**Author:**  [@sai-santhosh](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2Fsai-santhosh)%5C
**Post date:** [February 14, 2025, 3:37pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Fgetting-no-log-in-validation-loss%2F140868%2F3 "2025-02-14T15:37:28Z")
im working on conversational data, so i wont be able to create label\_names
---
**Author:**  [@John6666](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2FJohn6666)%5C
**Post date:** [February 14, 2025, 4:10pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Fgetting-no-log-in-validation-loss%2F140868%2F4 "2025-02-14T16:10:10Z")
Hmmm… I think I may have found a way to forcefully record it.
>
>
> Evaluations are being run, \_but no validation loss is logged or sent to WandB\_
> …
> The console shows that eval is running, but displays a table along the lines of:
>
> | eval loss | validation loss |
> |-----------|-----------------|
> | 1 | no log |
> | .9 | no log |
> | .8 | no log |
>
> WandB shows evidence validation run occurs, but doesn't display loss either:
> \ >
>
> \`\`\`
> from trl import SFTTrainer
> from transformers import TrainingArguments, DataCollatorForSeq2Seq
> from unsloth import is\_bfloat16\_supported
> import os
> os.environ\["WANDB\_PROJECT"\] = "my\_project" # name your W&B project
> os.environ\["WANDB\_LOG\_MODEL"\] = "checkpoint" # log all model checkpoints
>
>
> trainer = SFTTrainer(
> model = model,
> tokenizer = tokenizer,
> train\_dataset = train\_dataset,
> eval\_dataset=validation\_dataset,
> dataset\_text\_field = "text",
> max\_seq\_length = max\_seq\_length,
> data\_collator = DataCollatorForSeq2Seq(tokenizer = tokenizer),
> dataset\_num\_proc = 2,
> packing = False, # Can make training 5x faster for short sequences.
> args = TrainingArguments(
> fp16\_full\_eval = True,
> per\_device\_eval\_batch\_size = 2,
> eval\_accumulation\_steps = 4,
> report\_to = "wandb",
> run\_name = "run-name-here",
> per\_device\_train\_batch\_size = 4,
> gradient\_accumulation\_steps = 4,
> gradient\_checkpointing=True,
> warmup\_steps = 5,
> do\_predict=True,
> logging\_first\_step=True,
> num\_train\_epochs = 3, # Set this for 1 full training run.
> save\_steps = 88,
> evaluation\_strategy="steps",
> eval\_steps=88,
> do\_eval=True,
> learning\_rate = 1e-4,
> fp16 = not is\_bfloat16\_supported(),
> bf16 = is\_bfloat16\_supported(),
> logging\_steps = 1,
> optim = "adamw\_8bit",
> weight\_decay = 0.01,
> lr\_scheduler\_type = "linear",
> seed = 3407,
> output\_dir = "outputs",
> ),
> )
>
> \---
>
> from unsloth.chat\_templates import train\_on\_responses\_only
> trainer = train\_on\_responses\_only(
> trainer,
> instruction\_part = "\<|start\_header\_id|\>user\<|end\_header\_id|\>\\n\\n",
> response\_part = "\<|start\_header\_id|\>assistant\<|end\_header\_id|\>\\n\\n",
> )
>
>
> trainer.train()
> \`\`\`
>
> Very similar settings work when using plain SFTTrainer in another project