# Accelarator can't detect my GPUs?
**URL:**
**Author:**  [@Buggod](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2FBuggod)%5C
**Post date:** [March 28, 2024, 7:32pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F1 "2024-03-28T19:32:32Z")
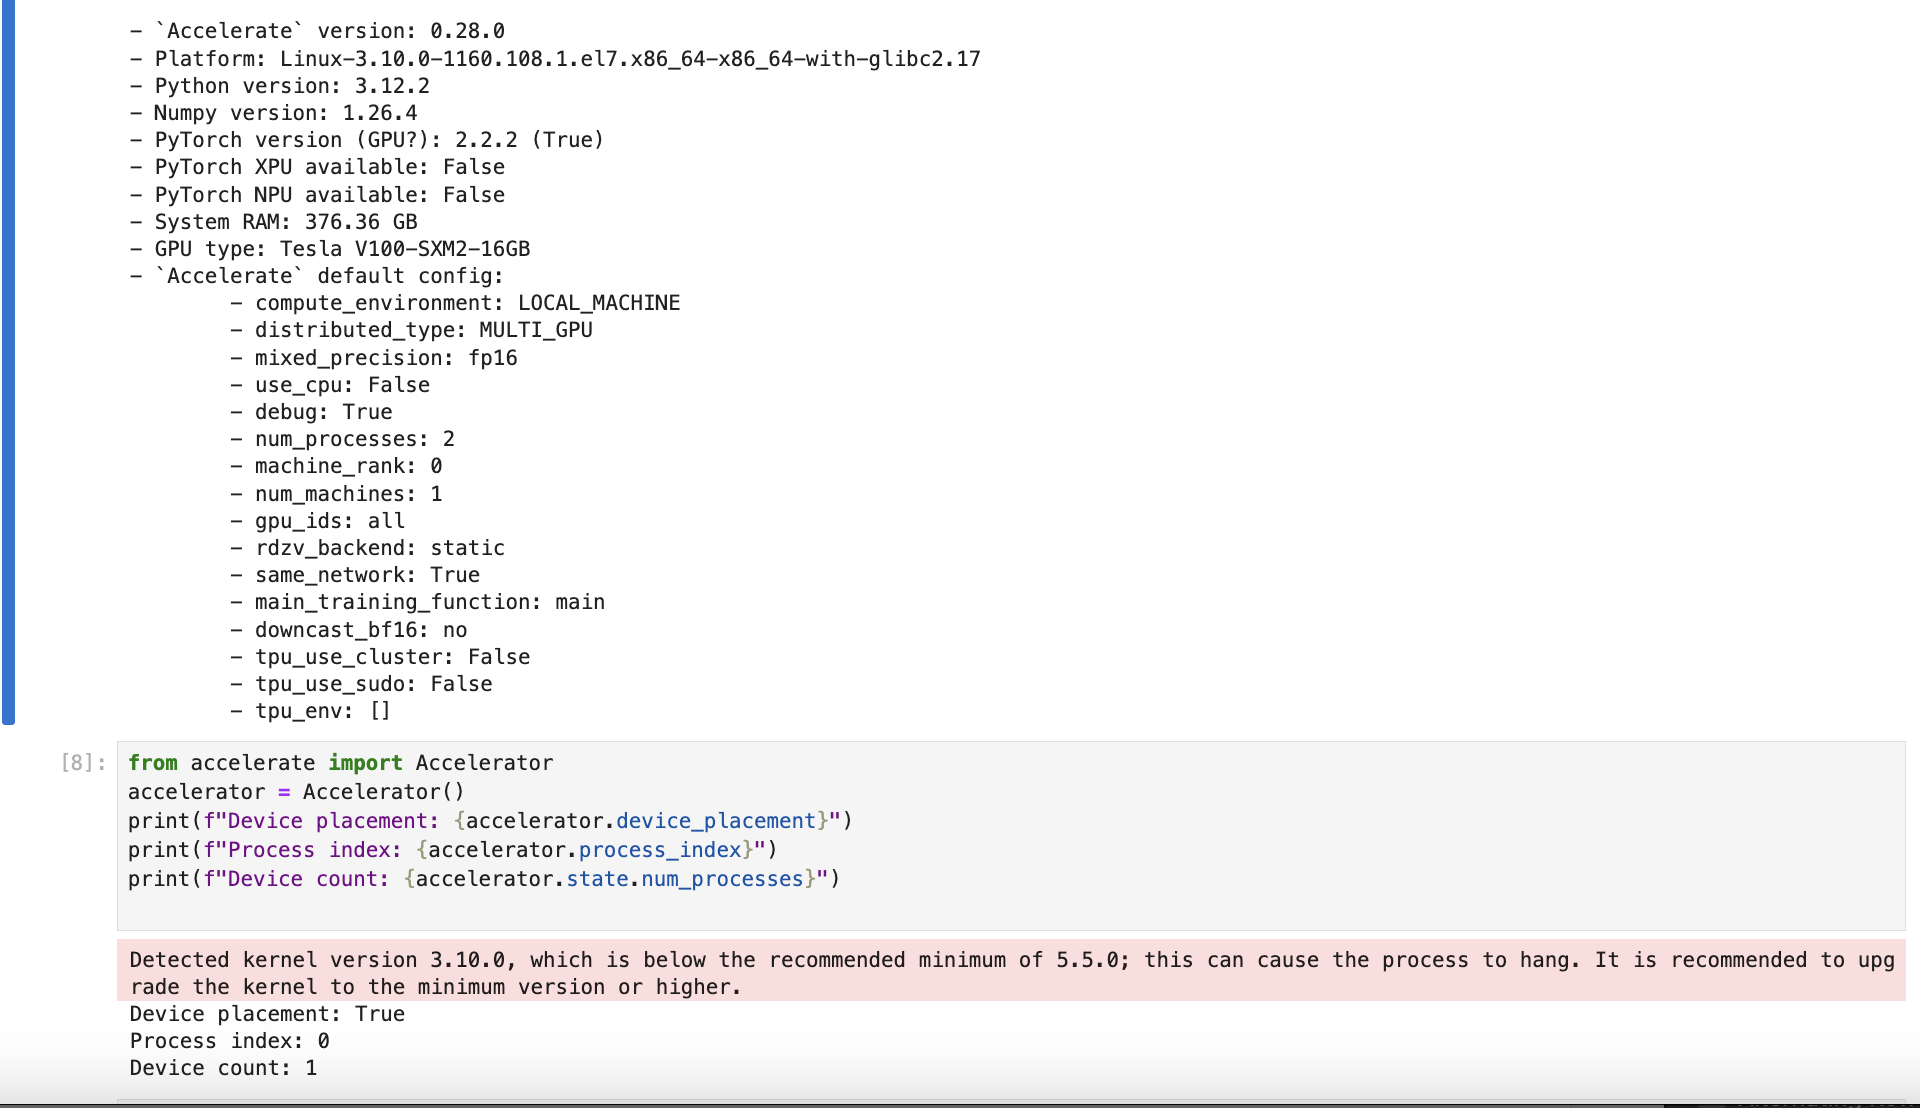
Is my config incorrect? I belive the kernel warning is not relevant to this issue.
Would appreciate any help! I really want to use two GPUs in parrallel to have more CUDA memory!
---
**Author:**  [@muellerzr](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2Fmuellerzr)%5C
**Post date:** [March 28, 2024, 7:38pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F2 "2024-03-28T19:38:06Z")
> [@Buggod](#):
>
> Would appreciate any help! I really want to use two GPUs in parrallel to have more CUDA memory!
You’re in a notebook, you need the notebook launcher 🙂 [Launching Multi-GPU Training from a Jupyter Environment](https://huggingface.co/docs/accelerate/basic_tutorials/notebook)
---
**Author:**  [@Buggod](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2FBuggod)%5C
**Post date:** [March 28, 2024, 7:48pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F3 "2024-03-28T19:48:42Z")
Thank vm for the reply!
Howeveer, I’m just trying to run inference on a server. The link is about training on different IPs? How to work on this with a single line of code? I feel like it’s gonna be super easy.
---
**Author:**  [@muellerzr](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2Fmuellerzr)%5C
**Post date:** [March 28, 2024, 7:58pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F4 "2024-03-28T19:58:03Z")
You’ll find running that code from a python file + `accelerate launch` or `torchrun`. will show what you want. This is a limitation of you working out of a Jupyter notebook session.
If you use regular big model inference it will do single parallel inference by loading one GPU after the next.
Here is an example of how to get distributed inference to work, which again requires the use of the `notebook_launcher` if using Jupyter.
> **[Distributed Inference with 🤗 Accelerate](https://huggingface.co/docs/accelerate/usage_guides/distributed_inference)**
>
> We’re on a journey to advance and democratize artificial intelligence through open source and open science.
---
**Author:**  [@Buggod](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2FBuggod)%5C
**Post date:** [March 28, 2024, 8:25pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F5 "2024-03-28T20:25:07Z")

Thank vm!
However, I still encounter issues. Can I know why ?
---
**Author:**  [@Buggod](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2FBuggod)%5C
**Post date:** [March 28, 2024, 8:25pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F6 "2024-03-28T20:25:37Z")

---
**Author:**  [@muellerzr](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2Fmuellerzr)%5C
**Post date:** [March 28, 2024, 8:26pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F7 "2024-03-28T20:26:36Z")
That means you ran out of CPU memory most likely (RAM)
---
**Author:**  [@Buggod](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2FBuggod)%5C
**Post date:** [March 28, 2024, 8:29pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F8 "2024-03-28T20:29:13Z")
Wow , I requested 50 GB. I’m running 2 V100 16 GB, so what’s the ideal RAM in this case?
---
**Author:**  [@Buggod](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2FBuggod)%5C
**Post date:** [March 28, 2024, 9:27pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F9 "2024-03-28T21:27:12Z")

Sir I fixed the memory issue but can I know what went wrong now?
---
**Author:**  [@muellerzr](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2Fmuellerzr)%5C
**Post date:** [March 28, 2024, 10:10pm UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F10 "2024-03-28T22:10:02Z")
Why are you using the accelerator as a context manager? What documentation are you going off of? That’s mentioned absolutely no where in any of our documentation. I’d highly recommend starting on our basic tutorials, such as the first one I linked there and this one [Handling big models for inference](https://huggingface.co/docs/accelerate/usage_guides/big_modeling)
---
**Author:**  [@Buggod](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Fu%2FBuggod)%5C
**Post date:** [March 29, 2024, 3:14am UTC](/static-proxy?url=https%3A%2F%2Fdiscuss.huggingface.co%2Ft%2Faccelarator-cant-detect-my-gpus%2F79187%2F11 "2024-03-29T03:14:59Z")
Sir upon reading those docs, I have following questions:
1. My project requires me to inference a LLM (requires 24+ GB in full precision) on two 16g v100s, it seems that Doc Distributed Inference 2nd and 3rd part is related to my request using accelerate. While the 1st part in the Distributed Inference Doc and big model inference aren’t relevant, while I’ve being trying to deploy them the whole night.
Am I correct?
2. While the 3rd part of the Distributed Inference being helpful, the 2nd part of it is missing in the doc, which I find most straightforward and relevant. The name is " 2. Loading parts of a model onto each GPU and processing a single input at one time" Can you please provide that part of doc to me?
Thank you very much!